

This article originally appeared on Weijin Research on Huxiu on August 23, 2026. Original Chinese title: 「DeepSeek、智谱与Kimi,竞争前沿生存空间」. It has been translated and adapted for an English-speaking audience.
At a Glance
Chinese models are moving from follower-style competition into genuine frontier competition. And the watershed of frontier competition is no longer just model capability, but the ability to keep producing frontier capability.
Compared with the tech giants that invest full-stack in compute, models, and applications, DeepSeek, Zhipu, and Moonshot AI (Kimi) face stronger resource constraints. They must keep producing intelligence at an ever-advancing frontier under those stronger constraints.
If parameters, compute, and capital can keep scaling but cannot be converted into revenue; if models can go global but cannot form a closed loop of data and commerce, then "scaling" is ultimately still just one expensive sprint, not a sustainable race.
The Cost of Scaling
Chinese open-source models have entered a new phase of parameter-scale expansion. From the second quarter onward, domestic AI models began moving into the trillion-parameter scale, and in the second half of the year, Kimi K3 raised that threshold to the 3-trillion level. This scaling trend will not stop anytime soon. After ByteDance executives internally declared "no distillation," they intend to push the competition even higher, to the 5-10 trillion level.
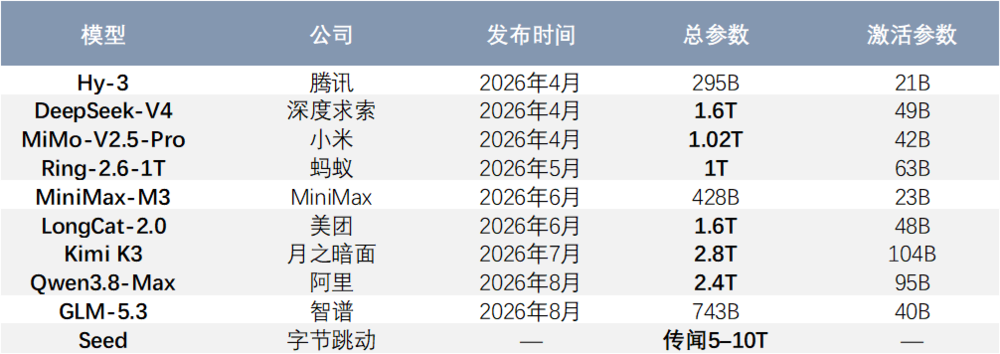
Table of Chinese AI models comparing release date, total parameters, and active parameters across companies such as Tencent, DeepSeek, and Xiaomi.
The race over parameter scale increasingly has to translate into a race over compute infrastructure, and the race over compute infrastructure will in turn translate into a race over capital. Both DeepSeek and Zhipu are building their own GW-level data centers.
Related: AI Competition: 3 Trillion Parameters at Home, GW-Scale Compute Abroad
In a widely circulated investor interview summary, Liang Wenfeng "aggressively" said that, if possible, he hoped to "spend all the money within half a year." This roughly corresponds to the first round of external financing of about 50 billion yuan, and a second round, now under way, that targets raising a further roughly 50 billion yuan. At the same time, the company is also preparing for an IPO.
The financing race has spread among domestic open-source model makers. As of the end of last year, Zhipu had about 2.3 billion yuan in cash and cash equivalents, raised about 4 billion yuan from its Hong Kong listing, and plans to raise 15 billion yuan on the STAR Market. MiniMax, likewise listed in Hong Kong, is also pushing for a dual listing. As for Moonshot AI, it completed cumulative financing of about $7.5 billion this year alone.
The tech giants are no exception. Over the past quarter, Tencent and Alibaba together spent about 120 billion yuan in capital expenditure on AI, putting increasing pressure on the free cash flow of both companies. Alibaba even announced a placement of new shares, planning to raise HK$80 billion for AI-related investment. This is its first share-placement financing since its Hong Kong listing.
The Constraints of Scaling
But compared with the tech giants, the pressure on DeepSeek, Zhipu, and Moonshot AI is more direct. They lack the cash flow of mature businesses, lack deep cash reserves, and find it hard to spread the cost of AI investment through internal resource allocation. For model makers, compute investment must ultimately be realized, almost entirely, through the commercial value of the models and products themselves.
The problem is that the combined annualized revenue (ARR) of OpenAI and Anthropic has already exceeded $100 billion, while, based on earlier official disclosures or market rumors, the combined ARR of the AI businesses of these three Chinese model makers, Zhipu, DeepSeek, and Kimi, may be only slightly above $2 billion over the same period.
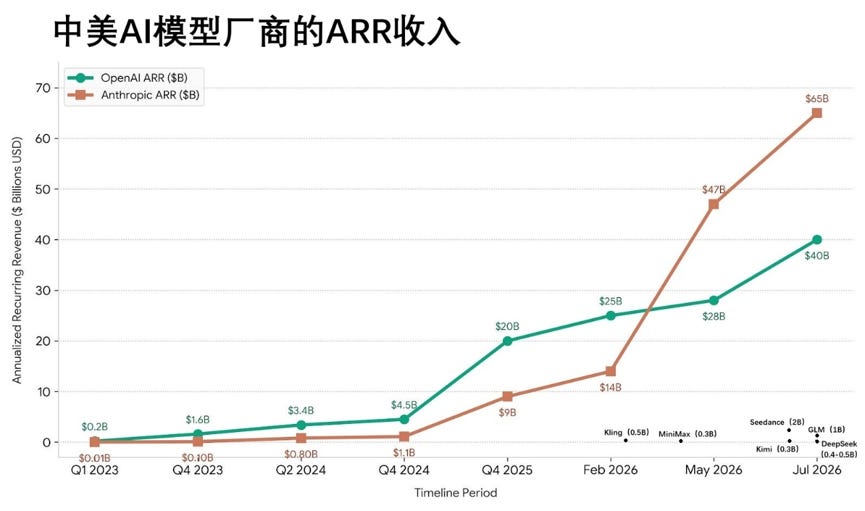
Line chart comparing annualized recurring revenue ($B) of OpenAI and Anthropic from Q1 2023 to Jul 2026, with select Chinese AI model vendors noted.
This of course partly reflects the gap in frontier model capability, but at the same time it also exposes the value-capture problem of open-source models, and the real gap between China and the United States in the scale of AI demand and in ability to pay.
Alibaba's latest earnings report provides an important reference for gauging the enterprise-market revenue headroom of domestic model makers. As of the previous quarter, in Alibaba's compute and cloud services segment, the ARR of AI-related products was about $7.3 billion. As infrastructure that carries a large volume of calls from third-party models and AI applications, this figure in fact reflects that the commercialization scale of Chinese models remains limited. If they rely mainly on the domestic enterprise market, their ARR obviously cannot grow out of thin air, detached from this industrial foundation.
This also means that once revenue growth cannot keep up with capital investment, valuation multiples quickly become a constraint on the ability to continue financing. At present, Zhipu's market cap is about $67 billion, MiniMax about $15 billion; DeepSeek's valuation is $71 billion, and Moonshot AI's about $50 billion. The implied valuation/ARR of China's leading model companies is already clearly higher than that of OpenAI and Anthropic.
When the domestic market is not yet sufficient to support this commercial closed loop on its own, the overseas market becomes an important part of revenue expansion. And the AI neoclouds and model routing services continually emerging in the U.S. market also make it easier for Chinese open-source models to embed themselves more deeply into the global model service ecosystem.
Deploying an open-source model onto their own compute infrastructure the moment it is released has become an important competitive approach for Nvidia-backed AI neoclouds such as CoreWeave. Earlier, Cursor fine-tuned models based on Kimi's open-source model; now, legal AI companies such as Harvey are also beginning to build their own enterprise-grade AI on Kimi-K3.
Moonshot AI has begun exploring the balance between open source and commercialization, setting a threshold, through its self-defined Kimi K3 License, for open-source models to move from being "widely used" to "being able to capture value."
The Paths of Scaling
Unlike full-stack tech giants such as Alibaba, Tencent, and ByteDance, DeepSeek, Zhipu, and Moonshot AI are more like "model-native companies" in the true sense, and they must convert model capability into external revenue more directly. The real difference among the three companies lies not only in model capability, but in which frontier-intelligence scaling path each has chosen.
In overseas markets, distillation remains a fairly sensitive issue. In particular, some institutions and organizations attribute the relentless advance of Chinese open-source models in frontier intelligence to "industrialized distillation"; but this is not an industry consensus. Rather than responding directly to this controversy, they seem more to be exploring, in their own way, where frontier intelligence should ultimately come from.
Right now, Kimi-K3 is betting again on pretraining scale, Zhipu is putting more compute into post-training, and DeepSeek is trying to bring infrastructure efficiency itself into scaling.
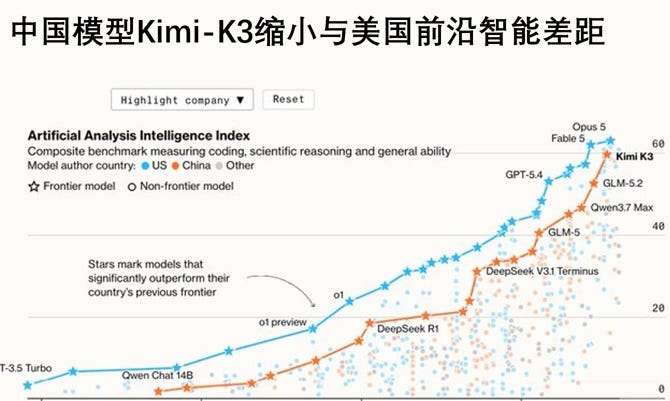
Chart comparing China and US frontier AI models on the Artificial Analysis Intelligence Index over time, highlighting Kimi K3's position near US models.
In some sense, the arrival of Kimi-K3 is also a correction to the catch-up path of "distillation + reinforcement learning." Earlier, Kimi had been called out by Anthropic over the question of where its model capability came from, and Kimi-K3 chose to bet again on pretraining scale. In a retrospective in its technical report, the Kimi-K3 team said that in the past, the short-term gains from test-time scaling masked the problem of insufficient pretraining scaling, and that this also became an important reason for the widening gap with frontier models. This strategy has at least made clear progress in the short term: Kimi-K3 has already approached frontier models on several key benchmarks.
Zhipu offers another answer. From GLM-5.2 to GLM-5.3, the team has improved capability on the same base model by scaling up long-horizon environments, task types, and reinforcement learning compute. What Tang Jie emphasizes is that one need not turn all the scaling "buttons" at the same time; rather, find the variable most worth investing in at the next stage. This has not only given GLM-5.3 an inference-cost advantage, it also fits better with Zhipu's existing commercial structure. The larger the model, the higher the demands on local compute supply, domestic hardware adaptation, and deployment cost. For Zhipu, where revenue from domestic government and enterprise clients and from private deployments still accounts for an important share, how to strike a balance between model capability and deployment cost is itself part of scaling.
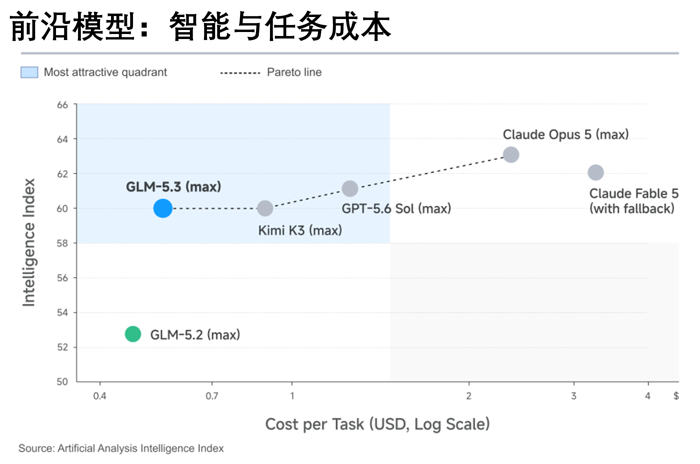
Scatter plot of frontier models' intelligence index versus cost per task (USD, log scale), with a Pareto line and highlighted most attractive quadrant. Source: Artificial Analysis Intelligence Index.
DeepSeek offers a third answer. It likewise believes that parameter-scale expansion has still not reached its ceiling, but its most distinctive feature is making infrastructure efficiency scale in tandem, as part of frontier-intelligence scaling. In other words, its model innovation also bears the burden of innovating the matching domestic hardware capability. It is said that DeepSeek is also seeking self-developed chips. As the bottleneck of frontier intelligence passes from parameter scale to compute scale, and then to hardware production capacity, infrastructure efficiency has become an unavoidable link in continuing to scale. This path is bound to be difficult, and precisely for that reason, important.
The market positions and competitive landscape in front of these companies are changing rapidly every day. The frontier competition between OpenAI and Anthropic is also constantly generating new technical paths, product strategies, and business models. For China's model-native companies, are they now competing mainly against OpenAI and Anthropic, or mainly among themselves?